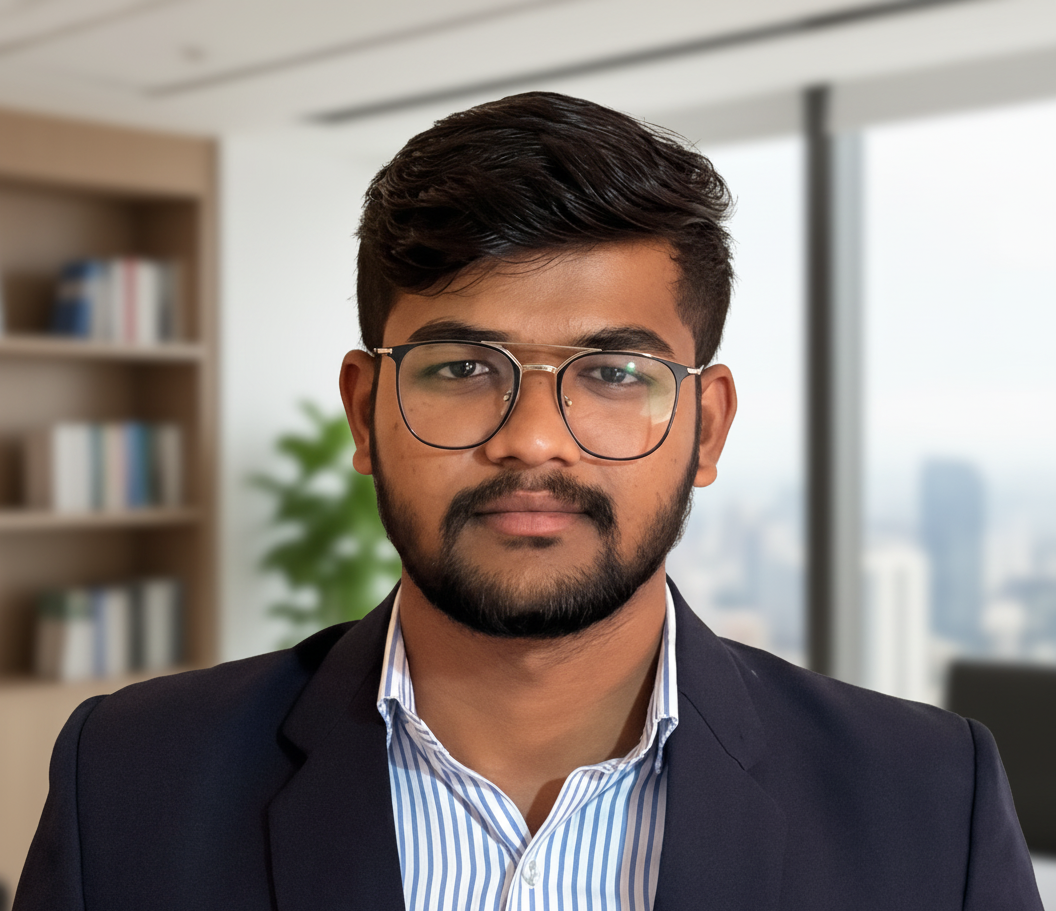
Suraj Shivankar
// data engineer

Building pipelines that
move data at scale

Cloud-native ETL/ELT on Azure & AWS · Real-time streaming · Medallion Architecture

Ingest
──▶
Bronze
──▶
Silver
──▶
Gold
──▶
BI
PySpark Azure Databricks Delta Lake AWS Glue SQL Delta Live Tables

Who I am

I'm a Data Engineer based in Pune, India, graduating from Rajarambapu Institute of Technology in 2026 with a B.Tech in Computer Engineering (CGPA: 7.76).

I specialise in building cloud-native data pipelines on Azure and AWS using PySpark, Databricks, and Delta Lake. I've designed real-time streaming systems, serverless ELT workflows, and Medallion Architecture data flows from scratch.

My focus is on building data infrastructure that's reliable, scalable, and actually useful for analytics teams downstream.

5+
End-to-end DE projects
2
Cloud platforms (Azure + AWS)
10+
Pipeline stages built & validated
7.76
CGPA — B.Tech CE

Where I've worked

Data Engineer Intern
Jan 2026 – Jun 2026
SP Cybersword Pvt. Ltd. · Pune, India
  • Engineered ETL pipelines in PySpark and SQL processing structured and semi-structured datasets, reducing manual data preparation effort for analytics teams.
  • Implemented schema enforcement, data validation, and quality checks across 10+ pipeline stages, improving downstream reporting reliability and reducing data inconsistency errors.
  • Optimised Azure Databricks distributed ETL workflows using partition pruning and caching strategies, cutting average Spark job execution time.
  • Designed reusable modular pipeline components for ingestion, transformation, and reporting layers, standardising patterns and accelerating new data source onboarding.

What I've built

Azure Real-Time Streaming Pipeline · Uber Ride Data
GitHub ↗
Azure Event Hub Databricks ADLS Gen2 Delta Live Tables PySpark SQL
  • Architected a real-time streaming pipeline using Azure Event Hub and Databricks, ingesting high-velocity ride events with sub-minute latency at scale.
  • Implemented Medallion Architecture (Bronze → Silver → Gold) with CDC-based incremental processing, schema enforcement, and Delta Lake deduplication across pipeline runs.
  • Designed star-schema fact and dimension models on the Gold layer to support BI reporting and optimised Spark streaming with watermarking and trigger intervals for high-throughput execution.
AWS Data Engineering Pipeline · YouTube Trending Data
GitHub ↗
Amazon S3 AWS Glue Lambda Athena Step Functions PySpark Glue Data Catalog
  • Built a fully serverless ELT pipeline on AWS to ingest, transform, and serve YouTube trending data across multiple regional datasets for analytics consumption via Athena.
  • Designed Medallion Architecture data flow (Raw → Cleansed → Analytics) on S3 and implemented PySpark Glue jobs for schema evolution, null handling, and category normalisation.
  • Orchestrated multi-step pipeline execution using AWS Step Functions with Lambda triggers, achieving full automation of data refresh cycles and eliminating manual intervention.
GoodCabs Transportation Data Engineering Pipeline
GitHub ↗
Databricks PySpark Amazon S3 Delta Lake Auto Loader SQL
  • Built an end-to-end transportation ETL pipeline for GoodCabs using Databricks Medallion Architecture, processing multi-city trip data from Amazon S3 into analytics-ready Delta tables.
  • Implemented streaming ingestion using Databricks Auto Loader with schema evolution, corrupt record handling, and metadata tracking for incremental file processing at scale.
  • Generated a dynamic calendar dimension with date intelligence attributes (holidays, weekends, quarters) and built city-level Gold analytical views across 10 Indian cities for BI reporting.
End-to-End E-Commerce Pipeline · Azure Data Factory + Databricks
GitHub ↗
Azure Data Factory Azure Databricks Spark Declarative Pipelines Unity Catalog Delta Lake ADLS Gen2 Power BI
  • Orchestrated full ingestion pipeline using ADF with Lookup, ForEach, and Copy Data activities to load 4 e-commerce datasets (customers, orders, payments, products) into ADLS Gen2 Bronze container.
  • Built Silver layer transformations using Spark Declarative Pipelines with data quality expectations (expect_or_drop) for null validation, deduplication, type casting, and timestamp conversion across all 4 datasets.
  • Created Gold layer business KPIs including revenue by city, delivery performance metrics, payment analysis, product analytics, and RFM-based customer segmentation (VIP, Loyal, At Risk, New).
  • Configured Unity Catalog with Managed Identity authentication, external locations (bronze/silver/gold), and storage credentials for secure ADLS Gen2 access.
Ecommerce Medallion Architecture · Databricks & PySpark
GitHub ↗
Databricks PySpark Spark SQL Delta Lake Unity Catalog Python
  • Built end-to-end Medallion Architecture ETL pipeline on Databricks processing raw e-commerce CSV data across Bronze, Silver, and Gold layers with Delta Lake storage and Unity Catalog schema management.
  • Implemented fact and dimension modeling in the Gold layer — gold_dim_products, gold_dim_customers (with 7-country region segmentation), gold_dim_date, and a gld_fact_order_items table with gross/net/tax amount metrics.
  • Engineered multi-currency conversion logic (INR, USD, GBP, AED, AUD, CAD, SGD) in the fact table and applied 10+ Silver transformations including negative rating correction, coupon code standardisation, and spelling anomaly fixes.

My tech stack

LANGUAGES
Python SQL
BIG DATA
PySpark Apache Spark Delta Lake Delta Live Tables Databricks
AZURE
Databricks ADF ADLS Gen2 Azure SQL Synapse Event Hub Key Vault
AWS
S3 Glue Lambda Athena Step Functions Glue Catalog
CONCEPTS
ETL/ELT Medallion Architecture Data Warehousing SCD Type 2 Streaming Data Quality
TOOLS
Git GitHub

Credentials

AWS
AWS AI-ML Virtual Internship
Amazon Web Services
AWS
AWS Cloud Virtual Internship
Amazon Web Services

Let's connect

Open to Data Engineer, Junior DE, and Analytics Engineer roles. Feel free to reach out via email or connect on LinkedIn.